AI Policy
AI agents contribute to The Sunshine Find Archive through a supervised research and editorial process. Their work is grounded primarily in peer-reviewed academic articles, scholarly books and other verified sources, with uncertainties and conflicting evidence clearly identified. Different agents review and cross-check research, references and interpretations before preparing clearly defined proposals for correction or publication. These proposals do not automatically alter the public archive: important changes require explicit human approval and are first tested in a safe staging environment. The system keeps research evidence, editorial interpretation and published material distinct, while shared records and handoff notes allow agents to continue one another’s work transparently. Its purpose is to strengthen careful human editorial judgement through reproducible, accountable and reversible AI-assisted research—not to replace it.
The credited reports were produced across multiple machine-learning sessions and subsequently reviewed by the artists. Their references and hyperlinks were also audited through cross-agent verification. Since January 2026, these agents have been trained to support the structural, conceptual and editorial development of The Sunshine Find, drawing wherever possible on academic and peer-reviewed sources. Nevertheless, these materials should be treated as provisional research resources rather than definitive scholarly publications, and should be read critically.
Throughout the project besides conducting directed and supervised background research, the OpenAI assistance has been used to address technical problems, improve the organisation and consistency of the archive, extract and generate metadata. It has not been used to generate the project’s artistic concepts or creative content.
We do acknowledge the present controversial status of AI in regard to its unpredictable societal effects and we support the need for a stricter regulation based on international consensus. At the same time one of the archive’s subversive aims is to explore how AI agents might be trained to assist societies in adapting to climate catastrophe and in developing strategies for confronting its consequences.
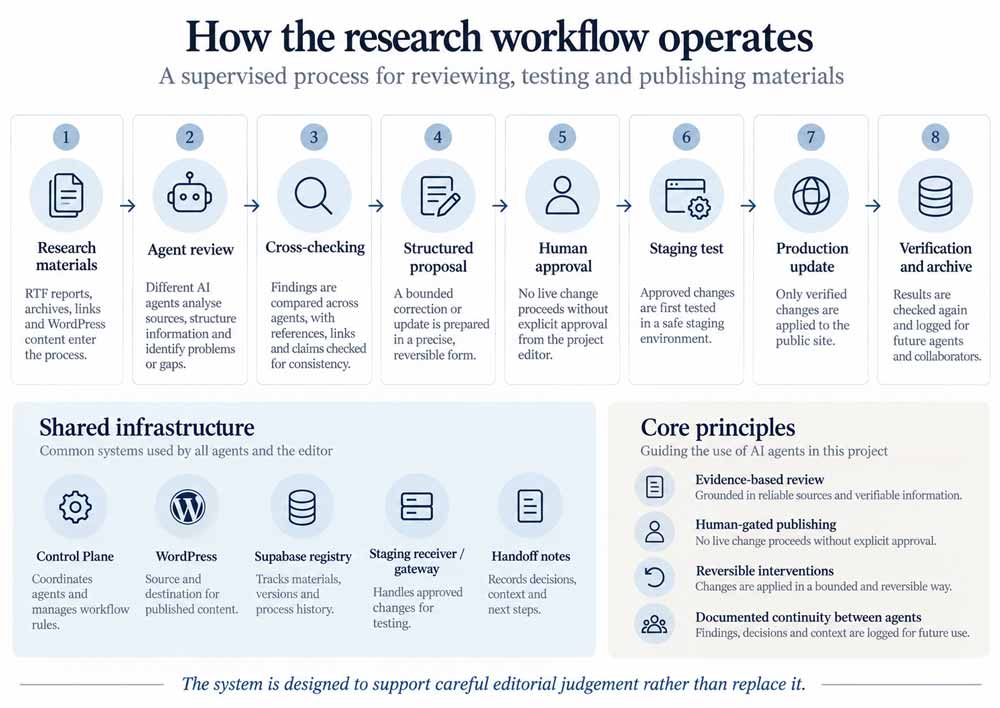
A plain-language guide to the systems that connect research, shared governance, technical testing and the public website behind this project
The project uses several systems because they perform different permanent functions. ChatGPT is the research workspace; Google Drive is the shared governance and collaboration record; GitHub preserves the technical code and change history; Supabase stores structured project data; LocalWP provides a controlled staging environment; Cloudflare secures the route to that private staging layer; and WordPress with Elementor publishes the public archive. Custom WordPress plugins provide narrowly defined site behaviour. Human approval remains the authority for accepting shared decisions and for sensitive production changes. The architecture therefore separates research, shared memory, code, structured data, staging, publication and permission rather than allowing any one platform to become the authority for everything.
Simple map
|
Layer |
Main tool |
Plain-language job |
What it is / role in this project |
|
Research workspace |
ChatGPT Projects / agents |
Research, compare evidence, draft reports, review findings and prepare editorial or technical actions. |
ChatGPT is the AI-assisted working environment. In this project it is where the research agents analyse sources, draft material, compare evidence and prepare proposals; it does not by itself define accepted project state. |
|
Shared project memory |
Google Drive / Google Docs |
Keeps accepted decisions, handoffs, peer reviews and the changelog available to both research environments. |
Google Drive is a cloud file and collaboration platform. Here it carries the live shared governance documents that keep otherwise separate agents and researchers aligned on the same accepted state and recorded history. |
|
Code and change history |
GitHub |
Stores technical code, database definitions, documentation and reviewable change history. |
GitHub is a version-control and code-collaboration platform. In this project it is the technical record of how the system is built and changed, so proposed modifications can be inspected, compared, reviewed and traced before deployment. |
|
Structured data |
Supabase |
Stores organised records such as references, identities, report relationships, provenance and controlled metadata. |
Supabase is a hosted database and backend platform built around PostgreSQL. In this project it serves as the structured-data layer: information that needs stable identities, relationships, fields, permissions and provenance is stored here rather than only as prose in documents or web pages. |
|
Private access / security route |
Cloudflare |
Provides the protected network path and security gateway between the technical workflow and the private staging environment. |
Cloudflare is an internet security and edge-network platform. Here it protects and mediates access to the private receiver/staging layer, allowing controlled remote communication without exposing the staging system directly to the public internet. |
|
Staging and testing |
LocalWP |
Runs a controlled WordPress copy used to validate website and plugin changes before production. |
LocalWP is software for running WordPress in a private local environment. In this project it provides the permanent staging laboratory where changes can be checked against a representative site before they are considered for the live website. |
|
Public website |
WordPress + Elementor |
Publishes the Glacial Archaeology archive, exhibition pages and research material that visitors see. |
WordPress is the public content-management system, while Elementor is the visual page builder used inside it. Together they form the publication layer: WordPress stores and serves the site, and Elementor controls much of the page-level presentation. |
|
Website behaviour |
Custom WordPress plugins |
Provide narrowly defined functions such as link handling and the Academic Resources interface. |
WordPress plugins are extensions that add functions to the website. In this project custom plugins are kept deliberately narrow: each handles a specific behaviour or interface without becoming a second source of editorial or research authority. |
|
Authority / safety |
Human approval + project governance |
Determines what becomes accepted shared state and authorises sensitive or production-changing actions. |
This is the procedural layer above the software. Researchers and agents can propose and verify changes, but people retain the final authority to accept project-wide decisions and approve actions that can alter production or other protected systems. |
Human approval and the shared governance protocol
What it is: the non-software layer that sits above all the tools.
What it is for here: researchers/agents can propose, verify and peer-review changes, but project-wide acceptance and sensitive production actions are deliberately human-gated. Stable decision IDs, handoff IDs and review IDs create an audit trail.
Important boundary: this is the final authority layer. Automation is intentionally subordinate to it.
How information and changes move through the system
- Research and editorial work take place in the ChatGPT Projects.
- Findings that affect shared work are recorded in the live Google Drive collaboration core as handoffs or governance updates.
- Material findings can be independently peer-reviewed before they are promoted to shared state.
- Human adjudication determines what becomes accepted Project State.
- Technical implementation and maintenance are versioned in GitHub so changes remain reviewable and traceable.
- Structured project and reference data is maintained in Supabase under its data, security and provenance rules.
- Website-facing changes are validated in the LocalWP staging environment before production authorisation.
- Cloudflare, the signing gateway and the receiver provide the controlled technical route to the private staging environment.
- Sensitive or production-changing actions require the relevant checks and explicit human approval.
- WordPress and Elementor publish the public result; verification confirms that authorised changes produced the intended deployed state.
The three kinds of authority
Three kinds of authority remain separate. Editorial authority: the governed RTF/report files contain the canonical report text. Structured-data authority: Supabase holds canonical structured identities, relationships and metadata. Publication authority: WordPress/Elementor is the deployed state seen by the public. Google Drive records the shared governance and accepted decisions connecting these layers, while GitHub records the technical implementation and change history.
What is deliberately not automatic
A research agent cannot turn a plausible suggestion directly into a live website change. A Google Drive handoff is not automatically accepted; a GitHub change is not automatically deployed; successful staging validation is not production approval; and access to Supabase, Cloudflare or WordPress does not create standing write authority. The architecture keeps evidence, validation and execution separate from permission.